Omer Develioğlu, co-founder of Northend Games, reported that his indie titles, Northend Tower Defense and Deepstone Rift (Early Access), generated a gross income of 0,000 from approximately 135,000 units sold on Steam over five years. After expenses and revenue sharing, he and his co-founder received only ,000 to split, resulting in an annual income of about ,000 each. A significant portion of their sales, around 53.3%, came from China. Steam charges a standard fee of 30% on sales, which deducted ,000 from their earnings. Additionally, U.S. withholding taxes reduced their total earnings further, leaving them with ,300.
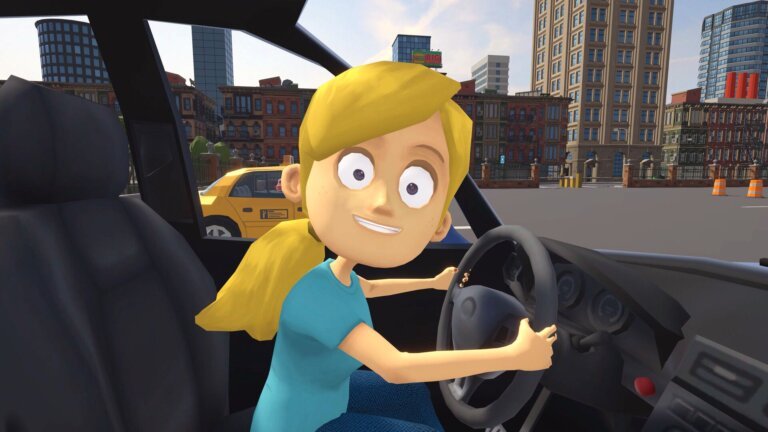
Artificial intelligence, particularly through large language models (LLMs), is expected to significantly impact the gaming industry by enhancing non-player characters (NPCs). However, practical implementation has been limited, with few titles like Where Winds Meet exploring this technology. A case study from the developers of Teach My Little Sister How To Drive highlights the financial challenges of integrating LLMs, as daily operational costs have exceeded ,000 due to high player interactions. The developers, Easy Fox, have taken out a bank loan to sustain the demo but are uncertain about its long-term viability. They are considering alternatives like local AI models for players with powerful GPUs, though this would limit accessibility. The game’s reliance on a premium LLM raises questions about its necessity, especially given existing design challenges such as artificial dialogue and misinterpreted commands. The full release of the game is scheduled for January next year.
Google is teasing the return of the Android Dev Summit, focusing on Android 18 and its visual transformation. Key upgrades include:
1. Modern Graphics: Introduction of multi-point mesh gradients and real-time progressive blurs for enhanced visual fidelity.
2. Evolved Material You: Development of tactile glassmorphism and fluid component scaling for a three-dimensional user experience.
3. App Efficiency: Stricter performance benchmarks to minimize resource-heavy background processes and ensure smooth operation.
4. Hardware Synergy: Optimizations in Android 18 designed to complement next-generation displays, particularly for the upcoming Pixel 12.
Valve has revealed that as of October 5, 2026, the Steam Machine has 47 verified games, surpassing the Steam Deck's 38 verified games. Three games—Dragon’s Dogma 2, Control Resonant, and The Blood of Dawnwalker—were upgraded from Unsupported on the Steam Deck to Verified on the Steam Machine. The Steam Machine's verification standard requires a resolution of 1080p at 30 frames per second, while the Steam Deck requires 800p at 30 frames per second. The Steam Machine is powered by hardware comparable to an AMD Radeon RX 7600M, while the Steam Deck uses a custom RDNA 2 APU. The analysis of the top 100 best-sellers shows that 38 games are Verified on Steam Deck and 47 on Steam Machine, with 28 playable on Steam Deck and 23 on Steam Machine. There are 19 Unsupported titles on Steam Deck and 15 on Steam Machine. Valve's compatibility documentation states that any game verified on Steam Deck is also guaranteed to be verified on Steam Machine.
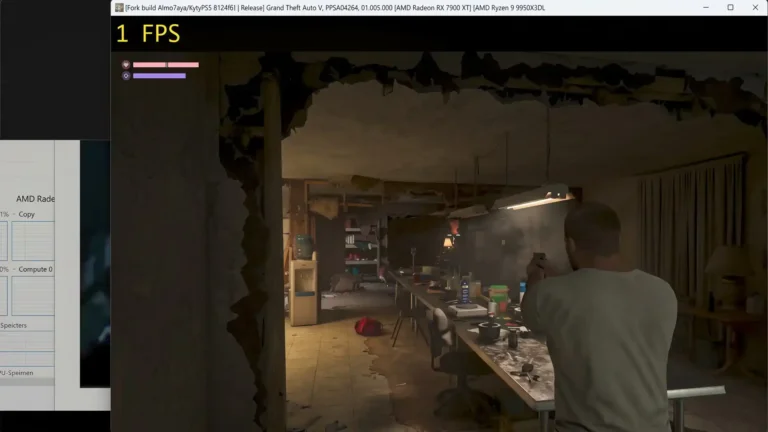
The gaming community is discussing the potential emulation of Grand Theft Auto VI on PCs, with its release scheduled for November 19th. Users are considering emulators like KytyPS5, SharpEmu, and RPCSX, but experts warn against downloading unreliable software such as PCSX5. The main challenge for emulation is the console's multi-layered security system, requiring developers to find vulnerabilities in the console's kernel and hypervisor. Current emulators can only handle basic games, and significant code optimization may take months to years. Legal challenges from Rockstar Games and Sony complicate efforts to distribute unauthorized game dumps. A stable PC port is seen as a distant goal, with the best experience expected on official consoles at launch.
Lakebase is a fully managed Postgres database designed for modern application development, featuring an architecture that separates storage and compute with a serverless compute layer. This design allows for cost efficiencies through various mechanisms:
1. **Branching**: Developers can create isolated environments for development, testing, or experimentation without duplicating storage costs, as branches share the same underlying storage.
2. **Autoscaling**: Lakebase adjusts compute resources based on activity levels, allowing users to pay only for the compute they use. It can scale down during low activity and can be suspended entirely after inactivity, reducing costs to zero.
3. **Read Replicas and High Availability**: The separation of storage and compute allows for adding read replicas and high availability without incurring additional storage costs, as these instances utilize the same storage layer.
4. **Synced Tables**: Integration with the Databricks Intelligence Platform enables efficient data syncing, allowing users to sync only the necessary working set of data, which helps avoid unnecessary storage and sync costs.
5. **Sync Modes**: There are three sync modes (Snapshot, Triggered, Continuous) for transferring data from the Lakehouse to Lakebase, each with different cost implications based on data freshness requirements.
6. **Right-sizing Compute**: Users can set the initial compute range during project provisioning to avoid over-provisioning and unnecessary costs.
7. **Monitoring and Metrics**: The Lakebase Metrics dashboard provides insights into working set size and cache utilization, helping users optimize their compute sizing and performance.
8. **Point-in-Time Restore (PITR) and Snapshots**: PITR maintains history for recovery within a configurable window, while snapshots offer discrete recovery points. Both are priced lower than standard storage, making them cost-effective options for data recovery.
Lakebase costs are categorized into compute, storage, and serverless pipeline compute for syncing data. Compute is measured by CU usage, while storage includes branch storage, PITR history, and snapshot storage, all tracked separately. Users can access detailed usage and cost information through system billing tables.
Amazon has introduced a new capability for Amazon Aurora PostgreSQL that allows users to query operational data alongside data stored in data lakes formatted in Apache Iceberg and Apache Parquet. This feature enables direct access to Iceberg REST Catalog-compatible catalogs, eliminating the need for data duplication or relocation. The integration of DuckDB within Aurora PostgreSQL allows users to query live operational data, including uncommitted writes, alongside data from data lakes using standard PostgreSQL syntax. This capability is available on Aurora PostgreSQL versions 17 (starting with 17.11) and 18 (starting with 18.6). Users must create an Aurora PostgreSQL cluster, attach an IAM role with the AuroraAnalytics feature, and enable the aurora_analytics extension to utilize this feature. They can create foreign tables referencing Iceberg or Parquet data in the data lake, and query them using familiar PostgreSQL commands. Aurora optimizes query performance through techniques like predicate pushdown and column pruning, and users can monitor query behavior with metrics provided by aurora_analytics_stat_statements(). Direct querying of Apache Iceberg and Parquet data is available across all commercial AWS Regions and AWS GovCloud (US) Regions without additional charges, aside from incremental Aurora compute and Amazon S3 request costs.
PostgreSQL 19 features an advanced query planner that utilizes table statistics from pg_statistic, gathered during the ANALYZE process, to generate and evaluate potential query plans based on their costs. The planner assesses various configurations, especially in complex joins, to select the most efficient option. Instances of poor planning are treated as bugs and addressed promptly. To improve query performance, users are advised to refresh statistics with ANALYZE, use CREATE STATISTICS for column correlations, modify indexes, and adjust memory settings. In cases where the query cannot be altered, providing planner advice may be necessary, particularly when the planner misestimates the output of PL/pgSQL functions or other custom functions, leading to inefficient query execution.
Amazon Web Services Inc. has enhanced its Aurora PostgreSQL database management system to allow users to query the Apache Iceberg data lake directly. This feature integrates the DuckDB analytical engine, enabling seamless access to live transactions and historical records without data duplication or complex ETL processes. Customers can use existing PostgreSQL applications to query data in Amazon S3, including S3 Tables. The integration aims to reduce the engineering workload associated with data pipelines and supports real-time applications.
DuckDB processes analytical scans within Aurora, eliminating extra network hops and allowing single queries to access both live and archived data. The feature supports external catalogs compliant with the Iceberg REST Catalog specification and can create foreign tables referencing data across multiple catalogs. Aurora optimizes query performance by filtering records and caching frequently accessed data.
Customers can combine recent transactions in Aurora with historical data from S3 without manual schema definitions. For low-latency workloads, selected data can be copied into native Aurora tables using standard SQL. This capability requires the aurora_analytics extension and an AWS IAM role for S3 and Glue access, and is compatible with Aurora PostgreSQL versions 17.11 and 18.6. The feature is available across all AWS regions at no additional charge, with costs incurred only for Aurora computing resources and S3 requests.