AppWizard
September 18, 2026
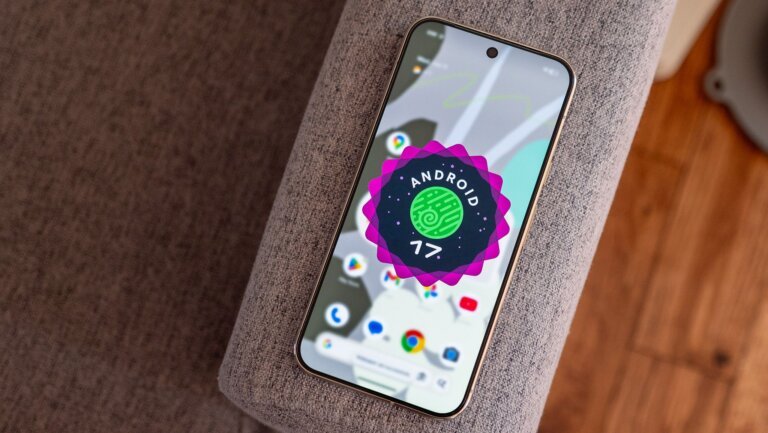
Google has launched Android Bench 2.0, a benchmark for evaluating large language models (LLMs) and AI agents on complex Android development tasks. This version focuses on long-horizon tasks (LHTs) that are more intricate than those assessed by the original benchmark. Key tasks include upgrading dependencies, adding major new features, and building Android apps from scratch. The new grading system uses continuous scoring instead of a binary pass-or-fail method, providing a more detailed performance evaluation. Currently, GPT-6 Astra leads the leaderboard with a 28% pass rate, followed by Gemini 3.8 Flash at 8%. Other evaluated models include Claude Fable 5.1, GPT-5.6 Sol, and Claude Opus 5. Google plans to expand the leaderboard with more models and results.