performance evaluation

AppWizard
September 18, 2026
Google has launched Android Bench 2.0, a benchmark for evaluating large language models (LLMs) and AI agents on complex Android development tasks. This version focuses on long-horizon tasks (LHTs) that are more intricate than those assessed by the original benchmark. Key tasks include upgrading dependencies, adding major new features, and building Android apps from scratch. The new grading system uses continuous scoring instead of a binary pass-or-fail method, providing a more detailed performance evaluation. Currently, GPT-6 Astra leads the leaderboard with a 28% pass rate, followed by Gemini 3.8 Flash at 8%. Other evaluated models include Claude Fable 5.1, GPT-5.6 Sol, and Claude Opus 5. Google plans to expand the leaderboard with more models and results.
AppWizard
July 13, 2026
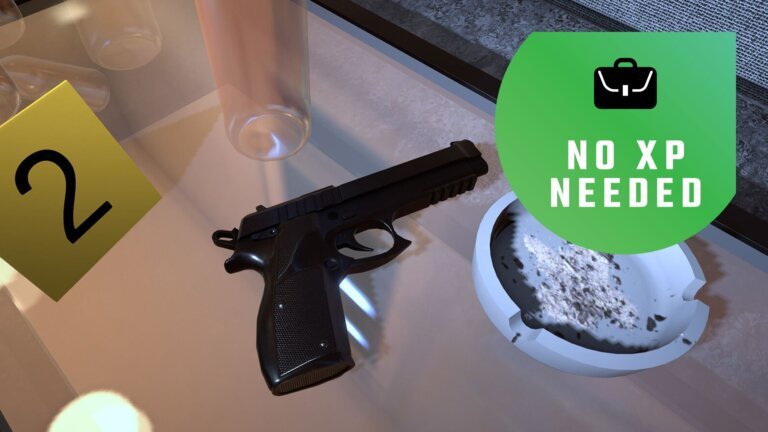
Chris Livingston is exploring job simulations to find a new career and is currently engaged in a Forensics: Crime Scene Detective simulation. His understanding of crime scene investigations is influenced by media portrayals, particularly CSI: Miami. In his first case, he successfully solves a bullet-in-wall scenario, scoring 100% after several attempts. However, he struggles with a coin burglary case, ultimately scoring only 16 out of 100 due to missed evidence and failed analyses. He reflects on whether he would enjoy being a real-life crime scene detective, finding the documentation appealing but the reality of blood and violence unappealing. Livingston appreciates the game's approach to failure, which allows for learning from mistakes.
AppWizard
May 26, 2026
Google launched the Android Bench benchmarking portal in March to help software developers evaluate AI models for Android app development. The leaderboard was updated last week to include open-weight models and new metrics for latency, tokens, and cost. Matthew McCullough, Google's VP of Product for Android Development, stated that the goal is to provide a benchmark for evaluating large language models (LLMs) in Android development. As of May 18, GPT 5.5 is the top AI model for Android app development, with Gemini 3.1 Pro and GPT 5.4 ranked as joint leaders. Android Bench evaluates LLMs based on real-world challenges and tasks sourced from public GitHub repositories. Other benchmarking tools in the Android ecosystem include Jetpack Microbenchmark, Jetpack Macrobenchmark, Firebase Performance Monitoring, Android Vitals, Apptim, and Android Performance Analyzer. The overall benchmark score on Android Bench is calculated using four core values: Confidence Interval Range, Average Latency Score, Average Total Tokens Score, and Average Cost. The test harness for Android Bench is publicly available on GitHub.
Search